When the shot gets harder, the tool matters.
@Kling_ai 4.0 is now in Luma for fast action and bigger camera moves.
Build with the best.
Created in Luma using multiple creative models, including Kling 4.0.
See the art direction on the product.
Start with your image, add 1–4 references, and Style Match restyles it while keeping the product and composition in place.
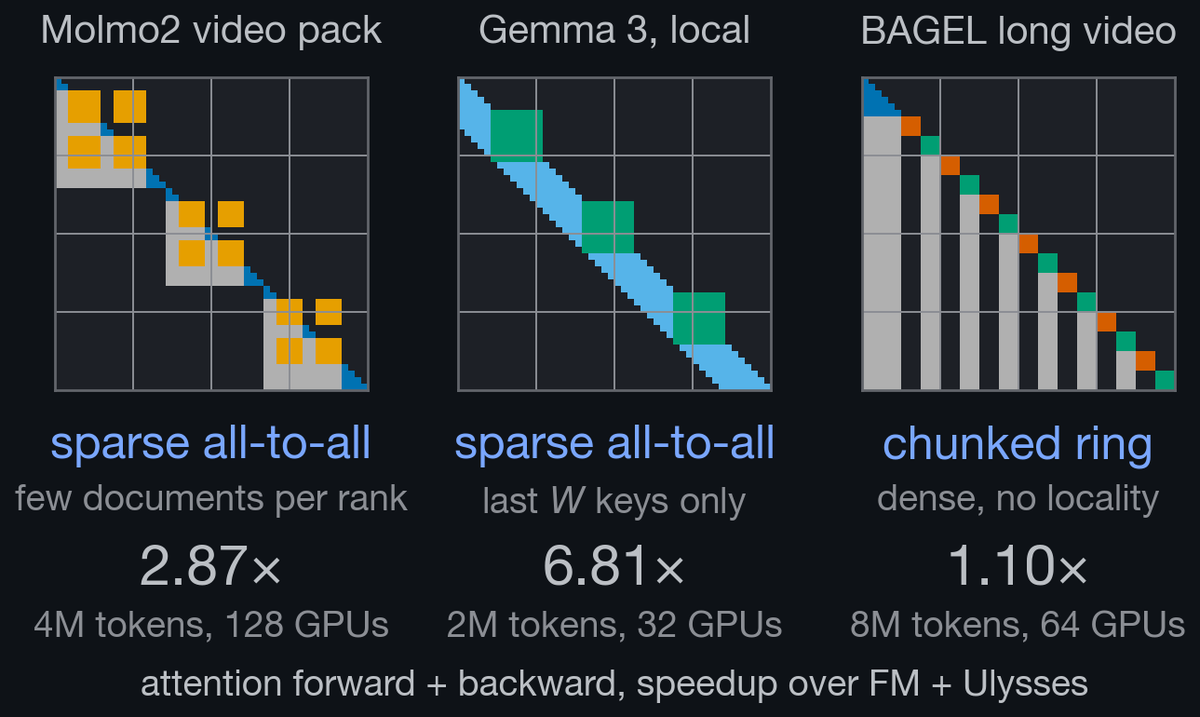
When queries see only a few samples, a sparse all-to-all fetches just the key/value blocks each rank needs, 55–100% fewer remote keys than ring attention on our sequences. For a sliding window, that is only the last window.
Standard ring attention rounds partial outputs to bf16 every step. Our online FlashAttention-4 kernel keeps the softmax state in fp32 across ring steps, so outputs and gradients match a single GPU.
Ring attention waits for its slowest rank at every step. We balance it with PTRR from PyTorch's context parallelism, applied to block-sparse costs: the busiest rank lands within 0.1% of the rest and the layer time roughly halves.
A packed sequence mixes causal text, bidirectional images and video, generated frames that only read earlier clean frames, and sliding windows. We plan all of it from per-token metadata and never build the full mask.
Exact sequence parallelism for packed multimodal masks.
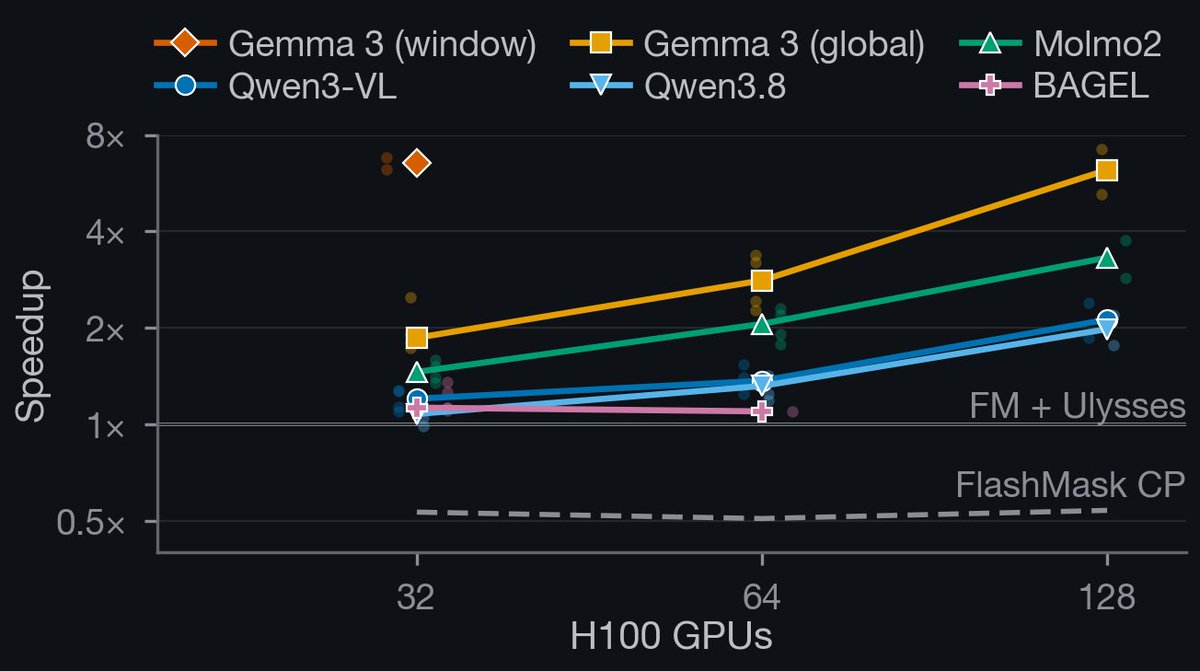
It picks ring attention, a sparse all-to-all or Ulysses per layer, matches single-GPU numerics, and beats a FlashMask + Ulysses hybrid in 47 of 48 cases on up to 128 H100s.
https://lumalabs.ai/news/packed-multimodal-attention
Inspired by Jackie Chan, Action Choreographer and Performance Lead Themo came to @DreamLabLA to learn how to strengthen control in some AI-motion tracked stunts.
We kicked off the preproduction with a planning session and then we went right to work capturing his motion in order