5buyai × AIFUNS
推广
← 返回资讯动态

DigitalOcean

@digitalocean
The AI-Native Cloud. ☁️ Status: @DOstatus Support: https://t.co/5gkvyionbi
227K关注者
278正在关注
89本站收录
30含视频
全部 图文 视频
A looping script can spend a month’s AI budget in an afternoon. Billing Insights now breaks your spend down by model, token type and access key. Spend Alerts can pause a model access key at the budget you set, now in public preview. Billing Insights: https://do.co/3U4auUj
7 1
在 X 上查看 →
Models ship every ~10 days. GPUs turn over yearly. Fabs, every half-decade. @neimuc27’s advice: never hard-code the model name. Put it behind a router so a swap is a config change, not a deploy. Commit to compute on the slow clock, choose models on the fast one. ⏱️
5 0
在 X 上查看 →
A new GPU can’t serve a token until the model loads. The article estimates a fully cold 70B start at 5–8 minutes. Warm nodes plus weight and engine caches cut it to 10–30 seconds, and engine startup becomes the bottleneck. https://do.co/3UT5X7p
11 1
在 X 上查看 →
RT @dicabrejas: Coding assistants on your laptop are great, but they don't scale to a full backlog. If you want to move from single-prompt…
0 3
在 X 上查看 →
DigitalOcean is on @Grok @bot. Sign in once, then ask in plain English to deploy to App Platform, launch Droplets, manage databases and DNS, or check what you’re spending. It shows a cost estimate before anything billable runs. https://x.ai/bot/plugin/79762613
23 6
在 X 上查看 →
A restored agent microVM starts running before its memory is loaded. Pages come from storage only when the guest touches them. On the warm-template path, request to serving traffic takes under 200 ms at p50 in our internal testing. https://do.co/4soRAnA
4 0
在 X 上查看 →
"Paste the API token into the prompt and hope” is not a security model. We let an agent run a real production migration across two clouds. It never held a credential, ran under an @NVIDIA OpenShell policy profile that locked writes to /workspace, and could only reach allowlisted
8 0
在 X 上查看 →
A model’s suggestion to call a tool is a request, not authority. Action Gateway keeps credentials out of model context and checks every tool call against policy: allow, deny, or ask a human. It aligns with @nvidia’s Open Agent Safety Platform. https://do.co/4ierrTS
9 1
在 X 上查看 →
Inference cost at scale is a routing problem before it’s a GPU problem. llm-d 1.0 went production-ready this month. It spreads token volume across the fleet to raise the cache-hit ratio. We run a forked version behind Serverless Inference and Managed Agents.
10 1
在 X 上查看 →
.@MiniMax_AI reports 73.67% on DeepSWE and 72.5% on AutomationBench-AA, which it calls the best result among open models. M3.1 Flash is now on DigitalOcean Serverless Inference and Dedicated Inference. $0.15 input, $0.60 output per 1M tokens. https://do.co/4xsz0fI
27 2
在 X 上查看 →
Over 90% of input tokens agents send us are tokens the model has already seen. Prompt Caching is now available on DigitalOcean Serverless Inference: cached input at up to 90% off, time to first token up to 80% faster, no code changes. Cache affinity keeps hit rates on flagship
16 3
在 X 上查看 →
RT @paddix: This week’s PHP2Shell disclosures and the AI-assisted attacks involving ConnectWise show how quickly the security equation is c…
0 2
在 X 上查看 →
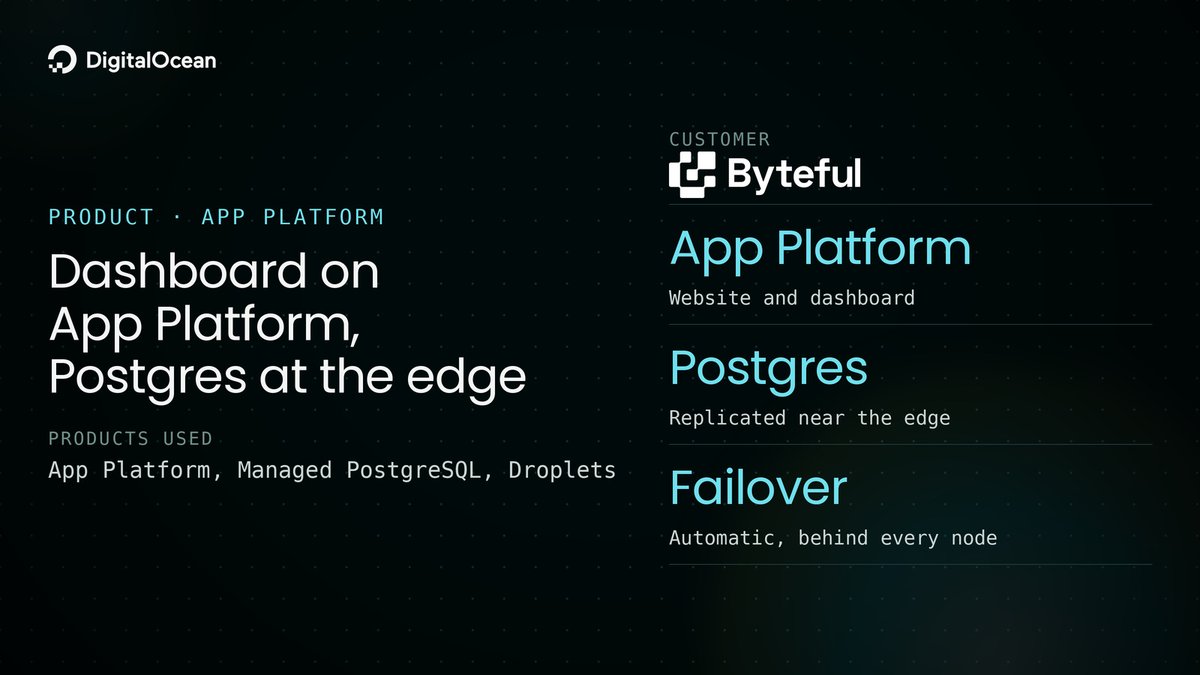
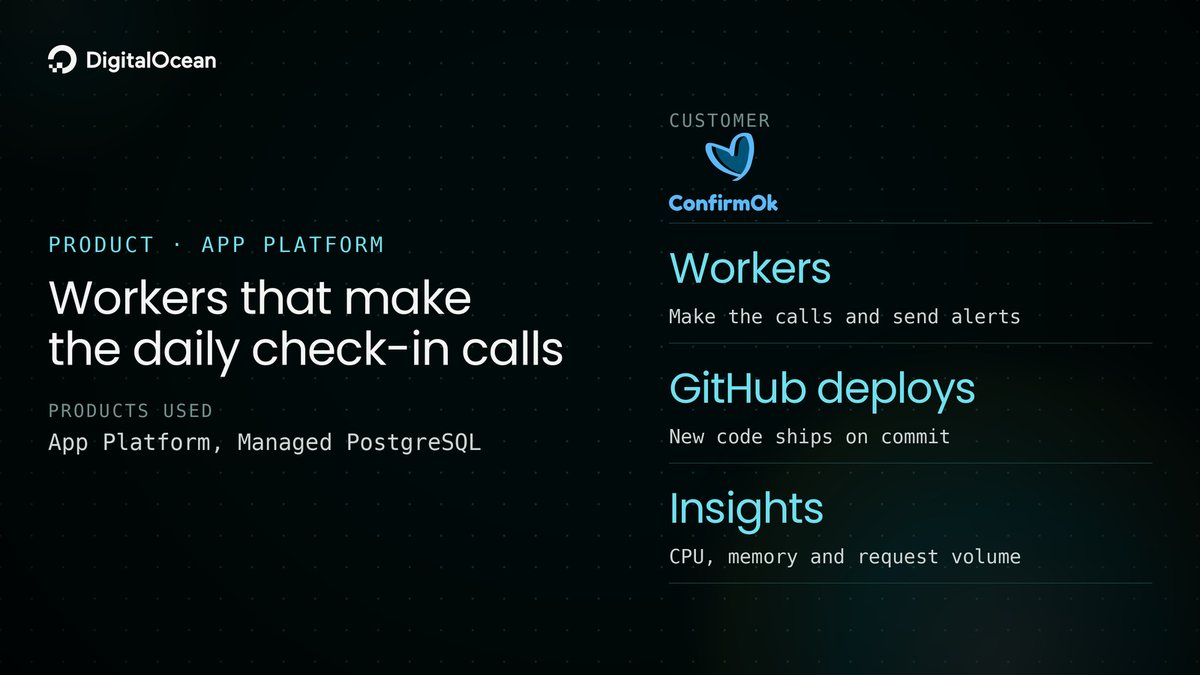
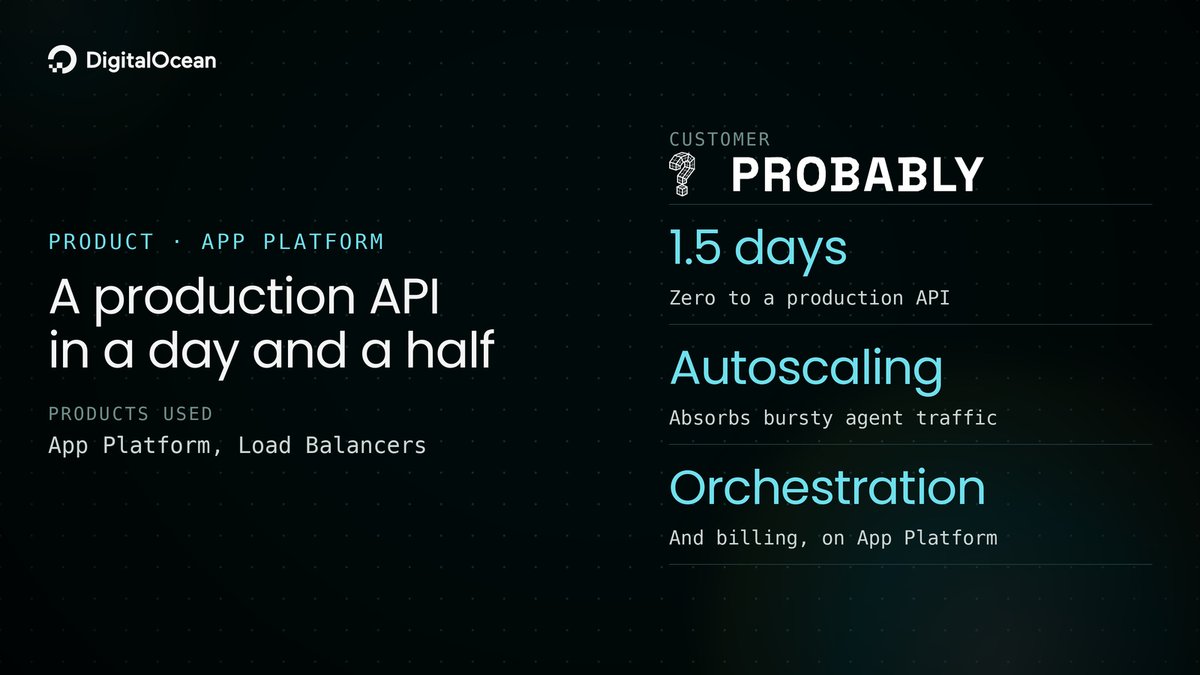
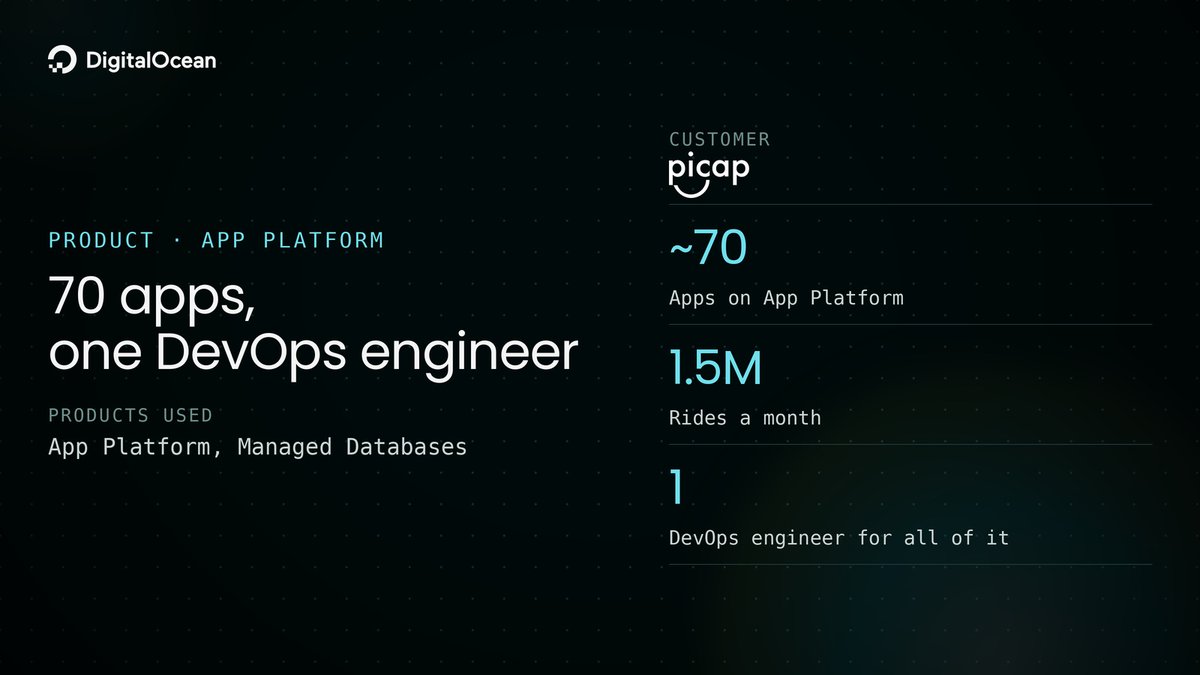
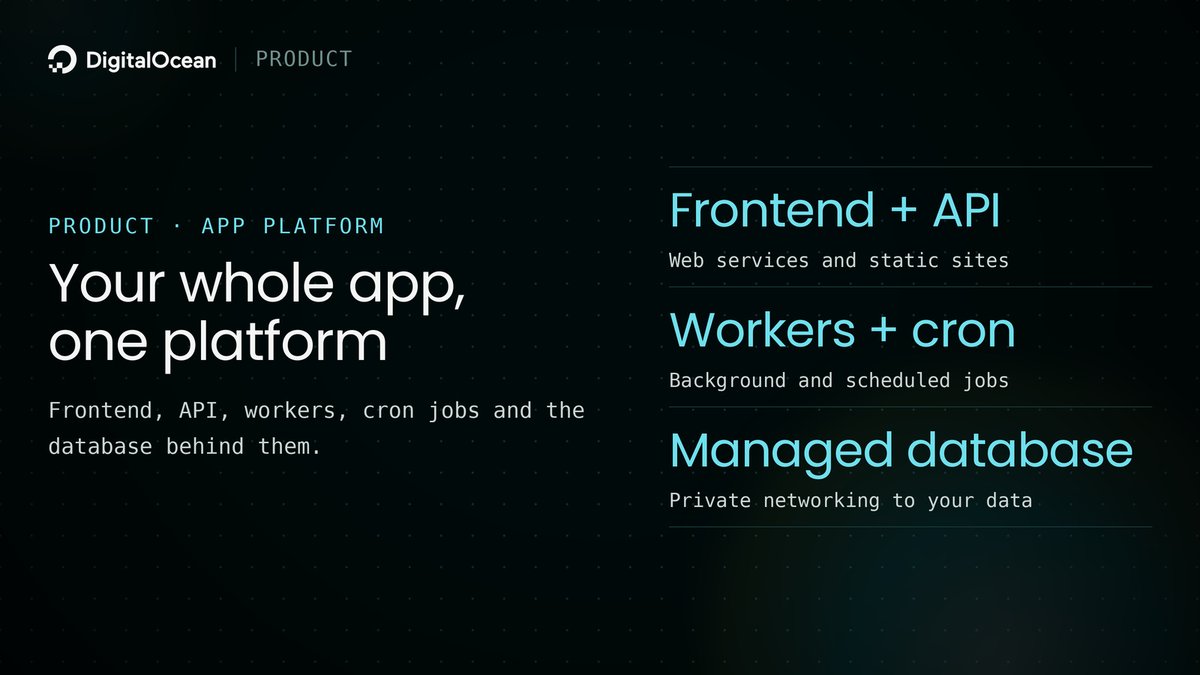
App Platform runs your whole app: frontend, API, workers, scheduled jobs, and the database behind them, with AI a function call away. One bill, private networking between services and data. Successful teams building on it: https://do.co/4dQnhjN 🧵
12 3
在 X 上查看 →
RT @ld_do_: Hey all, quick update: we tested a new UI with a small group of you, including a collapsible nav bar, and the feedback was loud…
0 2
在 X 上查看 →
以上内容聚合自 X 公开时间线,版权归原作者所有,点击可查看原文。本站与该账号无隶属关系。
✓ 始于 2024 年 ✓ 已服务 600+ 位买家 ✓ 累计成交 1,000+ 笔订单
需要帮忙吗?
购买 / 支付 / 账号问题,点这里问客服 →